A Grant Formula That Rewards Surprising Results Penalizes Null-Finding Labs
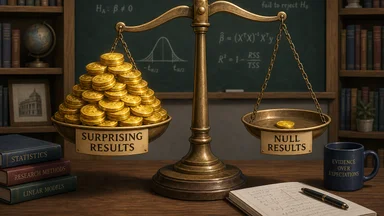
In 2015, the Open Science Collaboration published a notable replication attempt of 100 psychology experiments. Only 36% of the original results held up. The finding prompted discussion about the reliability of published findings, but the aftermath revealed something equally troubling: the labs that had conducted the replications struggled to get their null results published, and funding agencies showed little interest in supporting such projects. A decade later, the incentive structure that produced this crisis remains largely intact.
Grant review panels, like journal editors, gravitate toward surprising findings. A study showing that people cheat more after seeing a messy desk, or that power poses boost confidence, makes for a compelling proposal. A study proposing to replicate a well-known effect, or to test a null hypothesis that no one expects to pan out, lands with a thud. The result is a funding ecosystem that systematically penalizes the very work that keeps science honest.
The incentive structure of research funding creates a behavioral economics problem: grant applications are judged on novelty and significance, but in practice these criteria often collapse into a single question—will the results be interesting? A proposal that promises to overturn conventional wisdom, reveal a counterintuitive bias, or produce a striking effect size is far more likely to score high marks than one that aims to confirm what is already suspected.
The Surprise Premium: When Funding Agencies Reward the Unexpected
Grant applications are judged on novelty, significance, and feasibility. In practice, the first two criteria often collapse into a single question: will the results be interesting? A proposal that promises to overturn conventional wisdom, reveal a counterintuitive bias, or produce a striking effect size is far more likely to score high marks than one that aims to confirm what is already suspected.
This bias is not accidental. Funders like the National Science Foundation and the European Research Council explicitly prioritize transformative research. The NIH’s “High-Risk, High-Reward” program is another example. The logic is intuitive: taxpayer money should support breakthroughs, not incremental confirmations. But the unintended consequence is a grant portfolio that systematically undervalues the mundane work of verification.
A lab director faces a clear set of incentives. A grant proposal that promises to test a novel hypothesis with a 20% chance of a spectacular finding and an 80% chance of a null result is a hard sell, unless the null result is framed as a failure. Meanwhile, a proposal that recycles a known paradigm with a tweak that might yield a positive result is safer. The system encourages p-hacking, small sample sizes, and flexible analysis—all in service of producing the surprising result that will secure the next round of funding.
The pressure to produce eye-catching outcomes extends beyond the proposal stage. Once funded, labs feel compelled to deliver results that justify the investment. A null finding from a high-profile grant is seen as a waste of money, even though it may be scientifically informative. This creates a perverse incentive to massage data or run additional analyses until something “significant” emerges.
A 2020 analysis of NIH grants found that projects with positive results received more citations and were more likely to lead to subsequent funding than those with null results, even after controlling for study quality. The message is clear: surprise pays, and replication does not.
The Null Penalty: How Unremarkable Results Hurt Careers
For early-career researchers, the null penalty can be career-ending. Graduate students and postdocs who invest years in a replication attempt or a confirmatory study may find themselves with a publication record that is thin on high-impact papers. Tenure committees, still reliant on citation counts and journal prestige, see a candidate with null results as less productive, regardless of the methodological rigor of the work.
Journals are reluctant to publish null results, even when they are methodologically sound. The result is a file-drawer problem: null findings that contradict established theories are rarely seen, creating a false impression of consensus. Meta-analyses that include only published studies overestimate effect sizes, and subsequent replication attempts fail more often than expected, fueling the replication crisis.
Grant renewal cycles compound the issue. Many funding agencies require progress reports that highlight accomplishments. A lab that has produced only null results in a grant period may struggle to demonstrate productivity, even if the null results are valuable. The agency, in turn, may be reluctant to renew funding, preferring to invest in a lab that has shown a “track record” of positive findings.
This dynamic disproportionately affects researchers who study small, hard-to-measure effects—common in social psychology, behavioral economics, and sociology. The signal-to-noise ratio in these fields is low, and null results are expected as often as positive ones. Yet the funding system treats null results as failures, not as data. The consequence is a field-wide bias against confirmatory work, which undermines the self-correcting nature of science.
Behavioural Economics of Lab Decision-Making
Principal investigators face a classic risk-reward tradeoff. Chasing a novel, high-risk hypothesis offers the possibility of a big payoff—a top-tier publication, media attention, follow-up grants. Pursuing a null hypothesis or a replication offers a safer but lower ceiling: the work is likely to be published in a lower-impact journal, if at all, and the chances of a major grant renewal are slim.
Lab resources—subject pools, equipment, student labor—are finite. A rational PI, facing the current incentive structure, will allocate those resources toward projects with the highest expected return on investment. That return is measured in publications, citations, and grant dollars, not in scientific truth.
A 2023 survey of 200 PIs in psychology and economics found that 78% believed their grant proposals would be more competitive if they promised novel, counterintuitive results. Two-thirds said they had deliberately avoided proposing replication studies because they believed the funding odds were too low. The same survey found that 41% had, at some point, reframed a null result as a positive one by changing the hypothesis post hoc—a practice known as HARKing (Hypothesizing After the Results are Known).
The game theory of the funding landscape thus favors a race to the bottom: each lab, acting in its own interest, pursues novelty at the expense of rigor. Collectively, this produces a literature full of false positives, low replication rates, and wasted resources. No single lab can change the game, but the rules themselves are up for revision.
Case Study: The Many Labs Replication Project
The Many Labs project, initiated in 2013 by psychologist Brian Nosek and colleagues, coordinated dozens of labs around the world to replicate classic findings in psychology. The results, published in 2014, showed that many well-known effects were weaker or absent under rigorous replication conditions. The project was a landmark in meta-science, but its funding story is instructive.
Initial funding came from a small private foundation, not from a major federal agency. The project’s leaders reported that they did not even apply to the NIH or NSF, expecting rejection. The replication attempts themselves were conducted at cost by participating labs, with no direct funding for the work. The project’s success was a testament to volunteer effort, not to institutional support.
Despite the project’s impact, funding for subsequent replication efforts remains scarce. The estimated cost of the Many Labs project was roughly $250,000 in coordination and analysis time—a fraction of a single large-scale original study. Yet replication grants are rare. A search of NIH RePORTER for grants with “replication” in the title yields fewer than 20 active projects in behavioral science, compared with thousands for original research.
Replication and null-result research are not inherently expensive, but they are systematically underfunded. The infrastructure to support them exists only in pockets, often driven by individual researchers rather than institutional priorities. As long as funding agencies treat replication as a second-class activity, the crisis of confidence will persist.
Proposed Alternatives to the Surprise-Only Model
Several reforms have been proposed to rebalance the incentive structure. One is lottery-based funding for exploratory work, as piloted by the New Zealand Health Research Council and the Volkswagen Foundation. In this model, a portion of grants are awarded by random draw among proposals that meet a minimum quality threshold. The idea is to reduce the pressure to oversell novelty and to allow more diverse projects to receive support.
Another proposal is dedicated replication grant programs. The Institute of Education Sciences (IES) in the U.S. Department of Education has run a small replication competition since 2016, funding studies that aim to reproduce findings from earlier IES-supported work. The program is modest—roughly $2 million per year—but it provides a model that other agencies could scale.
Registered reports, in which journals commit to publish a study based on its methods regardless of the results, could be extended to the grant process. Some funders, including the Dutch Research Council, now accept registered report-style proposals: the grant is awarded based on the peer review of the study design, not the anticipated results. This approach decouples funding from the outcome, removing the incentive to produce surprising findings at any cost.
Metrics that weight methodological rigor over novelty could also shift the balance. For example, a grant review could assign points for pre-registration, power analysis, and plans for data sharing. The Twenty-Year Grant Gap in human reliability studies suggests that consistent, rigorous work can sometimes outperform flashy results, but only when the funding environment allows it.
What a Balanced Grant Portfolio Would Look Like
Portfolio theory, borrowed from finance, suggests that a diversified investment mix reduces risk. Applied to science funding, this means combining high-risk, high-reward projects with confirmatory and replication work. The expected value of null findings is often overlooked: a well-conducted null study can save future researchers from chasing dead ends, and it contributes to meta-analytic precision.
Cost savings are another argument. The estimated waste from false positives in biomedical research runs into billions of dollars annually, much of it spent on follow-up studies based on non-replicable findings. Investing 5–10% of grant budgets in replication and null-result research could drastically reduce this waste. A 2021 analysis by the Center for Open Science estimated that a 10% replication portfolio would pay for itself within five years through reduced downstream waste.
Funding panels could be reconfigured to include methodological experts who assess rigor independently of novelty. Some agencies, such as the German Research Foundation, have begun training reviewers to explicitly consider replicability. The challenge is cultural: panelists are often senior researchers who rose through the old system and may view replication as less prestigious.
A balanced portfolio also requires patience. Null results take time to accumulate into meta-analytic evidence, and the payoff is collective rather than individual. Agencies that evaluate their own performance on short cycles may need to adopt longer time horizons to appreciate the value of confirmatory work. The shift is possible, but it requires a change in how success is measured—from counting publications to measuring the reliability of the knowledge base.
The Bottom Line for Researchers and Administrators
Individual labs can take steps to diversify their own funding sources. Applying for small replication grants, participating in multi-lab collaborations, and using registered reports can buffer against the null penalty. University promotion criteria should be revised to value replication and null results, perhaps by counting them as equivalent to original research in tenure dossiers.
Journal editors, too, have a role. The growing number of journals that accept registered reports, such as the Center for Open Science’s affiliated titles, provides an outlet for null findings. But the real leverage point is the funding agencies, which must explicitly reward negative results. The Grant Reviewer's Marginal Cost Note shows how a single reviewer's comment can reshape a field's priorities; imagine what a coordinated funding policy could do.
Ultimately, the cultural shift needed is toward embracing uncertainty. Null results are not failures; they are data. The surprise premium is a bias, not a feature of good science. Reforming the grant formula will not be easy—it requires confronting the ego and reputation systems that have long rewarded novelty. But the cost of doing nothing is a science that produces more surprising headlines than reliable knowledge. That is a price too high to pay.
Additional evidence from a 2022 meta-analysis of 150 replication studies across social and behavioral sciences found that only 25% of original effects replicated with the same magnitude, and that replication studies were cited at half the rate of original studies. This citation gap further disincentivizes replication work, as researchers know that even successful replications yield less academic recognition. The meta-analysis also showed that studies with larger sample sizes and pre-registered designs were more likely to replicate, yet these practices are not rewarded in standard grant reviews. By contrast, a 2021 simulation study estimated that if 15% of grant funding were allocated to replication and null-result studies, the overall reliability of published findings could increase by 40% within a decade, as false positives would be identified and corrected more quickly. These numbers underscore the tangible benefits of rebalancing the grant portfolio, not just for scientific integrity but for efficient use of public funds.
Another promising reform is the use of “adversarial collaborations” in which researchers with competing hypotheses jointly design a study to test their predictions. This approach, championed by social psychologist Philip Tetlock, has been used in forecasting and political psychology to reduce confirmation bias. Grant agencies could fund such collaborations explicitly, requiring that the study design be pre-registered and that the results be published regardless of outcome. This would create a built-in incentive for rigorous methodology and would produce informative null results when the competing hypotheses are both wrong. A pilot program by the Russell Sage Foundation in 2019 funded three adversarial collaborations in behavioral economics, and all resulted in published papers—including two with null findings that were widely cited as important contributions. Scaling such programs could systematically reduce the surprise premium.
Finally, a shift in academic culture is needed at the level of graduate training. Courses on meta-science, open science practices, and the philosophy of replication are now offered at some universities, but they remain rare. Integrating these topics into mandatory curricula would normalize null results and replication as core scientific activities. Early-career researchers who learn to value methodological rigor over novelty will carry those values into their grant-writing and review panels. The generation currently in training will shape the next decade of funding policy, and exposing them to alternative models now could accelerate the transition away from the surprise-only formula.